Using Jev as an LLM Linter for OMP (Pi) Agent
1 distinct publishers across 2 articles (some outlets filed more than once).
Ownership mix: Other: 2
1 publishers · 2 articles · switch to 1-minute for disagreement and framing.
What happened
Semantic policy enforcement for coding agents, beginning with OMP and TypeSafe model-backed evaluation. - goulinkh/omp-semantic-policy
Why the coverage differs
AI-assisted comparison · labeled · generated just generated or not yet stored · not a verdict
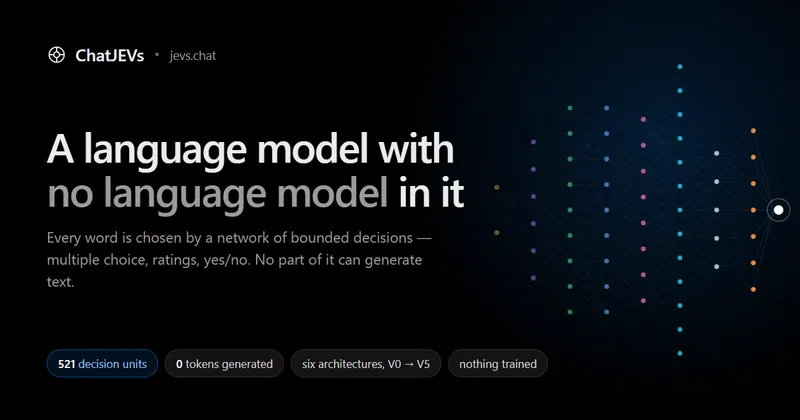
The cluster centers on the application of Jev, a decision-unit framework, to language model tasks. One project demonstrates an LLM constructed from 521 Jev models that assembles replies word-by-word without generating tokens. A second project applies Jev as a semantic linter for coding agents, specifically enforcing policy within the OMP environment.
Coverage diverges primarily in the technical focus of the implementations. The first source emphasizes the generative mechanics, highlighting the transparent probability behind each word choice in a zero-token generation process. The second source shifts the framing toward regulatory utility, focusing on semantic policy enforcement and model-backed evaluation for coding agents. Neither outlet addresses the underlying architectural similarities between the two distinct use cases.
Comparison summary
AI-assisted · Cerebras / Llama · just generated or not yet stored · inspect sources below rather than trusting this alone
The cluster centers on the application of Jev, a decision-unit framework, to language model tasks. One project demonstrates an LLM constructed from 521 Jev models that assembles replies word-by-word without generating tokens. A second project applies Jev as a semantic linter for coding agents, specifically enforcing policy within the OMP environment.
Coverage diverges primarily in the technical focus of the implementations. The first source emphasizes the generative mechanics, highlighting the transparent probability behind each word choice in a zero-token generation process. The second source shifts the framing toward regulatory utility, focusing on semantic policy enforcement and model-backed evaluation for coding agents. Neither outlet addresses the underlying architectural similarities between the two distinct use cases.
What is missing is any comparative analysis of performance metrics or accuracy benchmarks for these Jev-based systems. No source provides evidence on the efficacy of the semantic linter or the quality of the generated text. This omission leaves a blind spot regarding the practical viability of Jev as a general-purpose alternative to standard transformer architectures.
Report timeline
Oldest → newest among clustered members. Gaps may mean delayed pickup, not silence.
-
Sep 21, 2026, 6:29 AMChatJEVs · CenterI made an LLM using 521 Jev models
-
Sep 21, 2026, 8:52 AMGitHub · CenterUsing Jev as an LLM Linter for OMP (Pi) Agent
Coverage by perspective
Perspective labels are external consensus ratings (AllSides / Ad Fontes / MBFC-style), not WeSearch truth scores. Center is not automatically more accurate.
Center · 2
Headline framing
Vocabulary fingerprints · not a political endorsement
AI framing analysis temporarily offline. Configure Cerebras in admin to enable framing comparison.
Bias/ownership: published methodology on source profiles · AI text always labeled · no reader paywall · no engagement ranking of news · transparency · contribute Ws · home