AI for everyone in every language
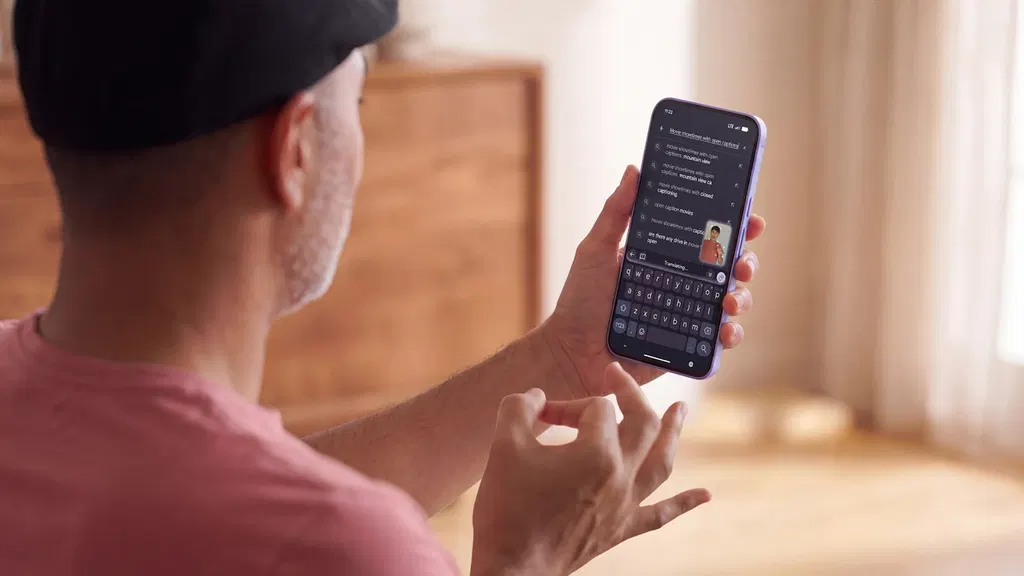
Instead of just translating text, they’re training AI to understand the emotion, tone, and slang people actually use in real life. They’re also working with local communities around the world to make sure their tools work for everyone, even those without reliable internet. This helps make sure that technology respects different cultures and helps people be understood on their own terms.
- ▪Instead of just translating text, they’re training AI to understand the emotion, tone, and slang people actually use in real life.
- ▪They’re also working with local communities around the world to make sure their tools work for everyone, even those without reliable internet.
- ▪This helps make sure that technology respects different cultures and helps people be understood on their own terms.
Google AI Blog files mainly under ai. We currently carry 26 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | Google AI Blog |
| Canonical URL | https://blog.google/innovation-and-ai/technology/ai/ai-for-every-language/ |
| Publication time | Tue, 15 Sep 2026 16:00:00 +0000 |
| Retrieval time | 2026-09-15T16:06:52.538Z |
| Last seen | 2026-09-15T16:06:52.538Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | None |
| Cluster logic | Not yet clustered, or no peer story found in the clustering window. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
{ "reading_time": "[[read\u002Dtime]] min read" } Breadcrumb Home Innovation & AI Technology AI AI for everyone in every language Sep 15, 2026 | x.com Facebook LinkedIn Mail Copy link We’re moving beyond traditional text translation to build models that understand the world’s rich, living languages exactly as they are expressed. James Manyika SVP, Research, Labs, Technology & Society Share x.com Facebook LinkedIn Mail Copy link { "play_video": "Play video", "pause_video": "Pause video", "mute": "Click to mute audio", "unmute": "Click to unmute audio", "enable_cc": "Enable Closed captions", "disable_cc": "Disable Closed captions", "disable_ad": "Disable audio description", "enable_ad": "Enable audio description", "video_progress": "Video progress", "aria_value_text": "elapsed time:…
Excerpt limited to ~120 words for fair-use compliance. The full article is at Google AI Blog.
Discussion
0 commentsMore from Google AI Blog