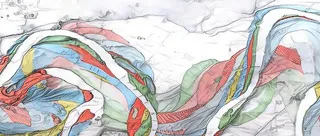
AI safety field *visual* impact analysis
A new terrain-style visualization maps the impact of 3,466 AI safety works by organizing them into 18 sub-fields based on citation counts and embedding space clustering. The interactive tool allows users to filter by time, researcher, and citation volume to observe how the field has evolved from 2021 to 2026. Key findings indicate that while adversarial robustness and interpretability have higher work volumes, alignment training and scalable oversight currently dominate in citation impact due to a few highly cited papers.
- ▪The visualization uses log-compressed citation counts to determine the height of terrain hills, representing the volume and impact of specific research areas.
- ▪Alignment training and scalable oversight currently have the highest citation counts, driven significantly by papers like InstructGPT and DPO.
- ▪Adversarial robustness and interpretability contain more total works than alignment training but receive fewer citations per paper.
- ▪The dataset includes 3,989 named authors and allows filtering by individual researcher to track their specific contributions within the field.
- ▪The analysis acknowledges that citation counts may not perfectly reflect actual safety impact and excludes LessWrong posts from the terrain due to indexing limitations.
Hacker News (AI / LLM) files mainly under ai. We currently carry 6,662 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | Lesswrong |
| Canonical URL | https://www.lesswrong.com/posts/fqpSosGwSt3uiZq35/ai-safety-field-visual-impact-analysis |
| Publication time | Mon, 28 Sep 2026 07:02:39 +0000 |
| Retrieval time | 2026-09-28T07:06:12.659Z |
| Last seen | 2026-09-28T07:06:12.659Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | Di-6JP8T02UE · 1 stories |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
I made a terrain style visualisation of AI safety impact of around 3,466 works organised by citation count! The data was extracted from Arxiv and LessWrong posts based on a dictionary of keywords that appear in AI safety works. Additionally, I think its important to see how the field has “evolved” over time so I added a time functionality to slide and see the hills forming.The map is based on how particular works overlap based on embedding space level clustering organised across 18 sub-fields.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at Lesswrong.
Discussion
0 commentsMore from Lesswrong