Bito's AI Architect Boosts Claude Opus's task success rate by 35%
Bito's AI Architect has significantly improved the task success rate of the Claude Opus coding agent by 35%. The evaluation conducted on the SWE-Bench Pro benchmark demonstrated that incorporating deep system context enhances performance, especially in complex coding scenarios. This advancement allows for faster task completion and greater efficiency without increasing costs.
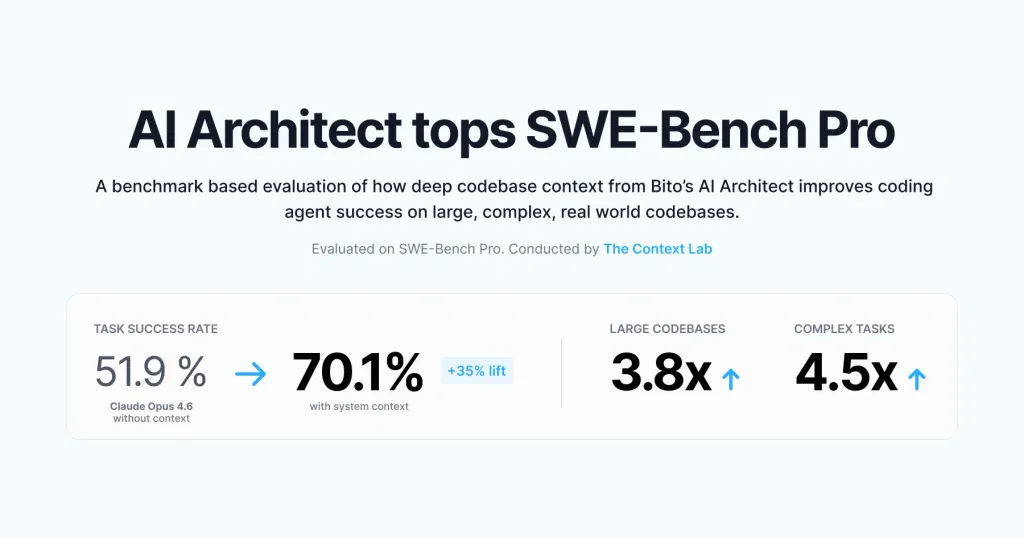
- ▪The task success rate for Claude Opus increased from 51.9% to 70.1% with the implementation of Bito's AI Architect.
- ▪Performance improvements are most notable in large codebases and multi-file changes, with success rates increasing by 3.8x and 4.5x respectively.
- ▪The average task duration decreased from 377 seconds to 300 seconds, and there were 25% fewer tool calls required per task.
Hacker News (Newest) files mainly under programming. We currently carry 5,305 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | Bito |
| Canonical URL | https://bito.ai/benchmarks/swe-bench-pro-evaluation/ |
| Publication time | Tue, 19 May 2026 10:02:03 +0000 |
| Retrieval time | 2026-05-19T10:04:57.575Z |
| Last seen | 2026-05-19T10:04:57.575Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | 6uCK8WuYEVv7 |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
AI Architect tops SWE-Bench Pro A benchmark based evaluation of how deep codebase context improves coding agent success on large, complex, real world codebases. Evaluated on SWE-Bench Pro. Conducted by The Context Lab Start free See key results TASK SUCCESS RATE 51.9% Claude Opus 4.6 Without context 70.1% with system context LARGE CODEBASES 3.8x COMPLEX TASKS 4.5x Even advanced coding agents resolve fewer than 52% of tasks when changes span large codebases and require coordinated, multi-file updates. These long-horizon scenarios expose a gap in system-level reasoning that most coding agents lack today. This evaluation examines whether structured system context can close that gap.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at Bito.
Discussion
0 commentsMore from Bito