BrowserAct AI Web Scraper in 2026: Build Once, Run Repeatedly
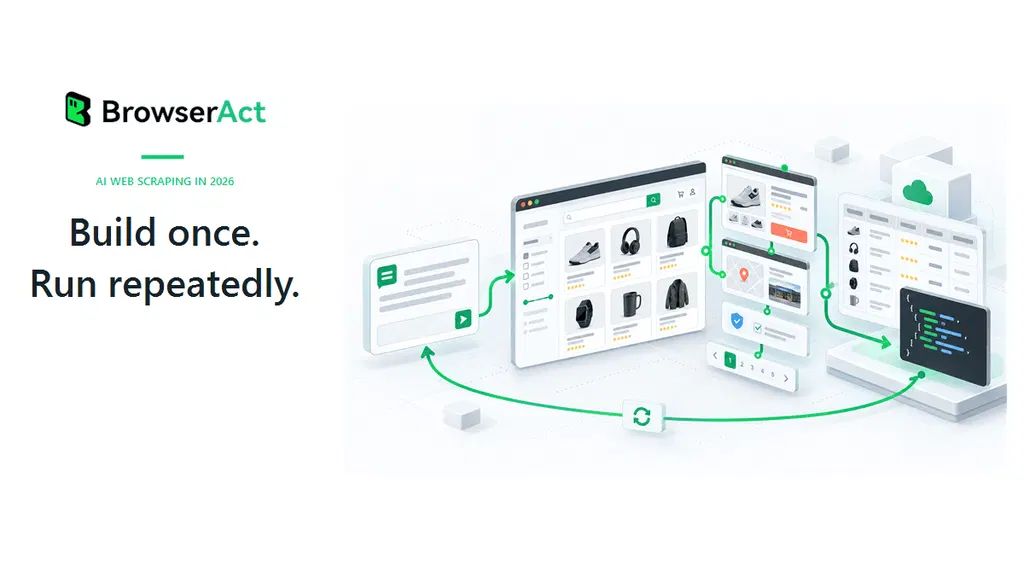
Sponsored Content Tracking competitor prices, updating product rankings, and collecting supplier information often means searching, filtering, paging through results, and combining data from different pages. BrowserAct AI web scraper can simplify the work, but recurring tasks still need a reusable path. Repeat the job every week, and the overhead adds up: scripts need maintenance, while an AI agent that explores the site afresh consumes more time and tokens.
- ▪Sponsored Content Tracking competitor prices, updating product rankings, and collecting supplier information often means searching, filtering, paging through results, and combining data from different pages.
- ▪BrowserAct AI web scraper can simplify the work, but recurring tasks still need a reusable path.
- ▪Repeat the job every week, and the overhead adds up: scripts need maintenance, while an AI agent that explores the site afresh consumes more time and tokens.
KDnuggets files mainly under ai. We currently carry 90 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | KDnuggets |
| Canonical URL | https://www.kdnuggets.com/2026/09/browseractai/browseract-ai-web-scraper-in-2026-build-once-run-repeatedly |
| Publication time | Thu, 01 Oct 2026 17:42:13 +0000 |
| Retrieval time | 2026-10-01T17:42:31.850Z |
| Last seen | 2026-10-01T17:42:31.850Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | ddMbWkn0DsjQ · 1 stories |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
Sponsored Content Tracking competitor prices, updating product rankings, and collecting supplier information often means searching, filtering, paging through results, and combining data from different pages. BrowserAct AI web scraper can simplify the work, but recurring tasks still need a reusable path. Repeat the job every week, and the overhead adds up: scripts need maintenance, while an AI agent that explores the site afresh consumes more time and tokens. Why Traditional Web Scraping Tools Struggle With Complex Websites A stable HTML page is usually straightforward to scrape. Traditional web scraping tools face more work when a task needs to wait for JavaScript rendering, submit a search, apply filters, move through results, and visit each detail page.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at KDnuggets.
Discussion
0 commentsMore from KDnuggets