DeepSeek-v4.1 Flash: Pushing the Limits of KV Cache Compression
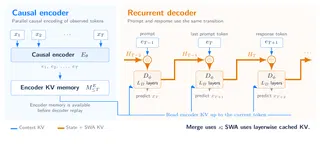
DeepSeek-V4.1 Flash is a 552B parameter multimodal mixture-of-experts model designed to optimize KV cache compression for long-horizon agent workflows. The architecture achieves nearly 420 tokens per second by reducing prefill computation and compressing the KV cache by a factor of four. These optimizations address storage and bandwidth bottlenecks to enable efficient processing of contexts up to one million tokens.
- ▪DeepSeek-V4.1 Flash utilizes a 552B parameter scale and supports multimodal inputs with a context window of up to one million tokens.
- ▪The model reduces prefill activated parameters to 8B by using only 20 of its 40 layers during the prefill phase, inspired by YOCO.
- ▪KV cache compression is achieved through head count reduction, block-based compression, cross-layer compression, and FP4 numerical precision.
- ▪The architecture combines Sparse Attention with Sliding Window Attention to manage long sequences while minimizing persistent storage requirements.
- ▪DeepSeek-V4.1 Flash is positioned as a significant architectural advancement that addresses the scaling limits of previous DeepSeek-V4 Pro models.
Hacker News (Front Page) files mainly under programming. We currently carry 1,740 of its stories. Top-voted stories on Hacker News.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | Github |
| Canonical URL | https://zartbot.github.io/blog/model_arch/dsv41flash_arch/en.html |
| Publication time | Thu, 17 Sep 2026 01:39:47 +0000 |
| Retrieval time | 2026-09-17T02:28:41.759Z |
| Last seen | 2026-09-17T02:28:41.759Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | ZPJOZvw8kVH1 · 1 stories |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
Essay · Model Architecture DeepSeek-V4.1 Flash:Pushing the Limits of KV Cache Compression zartbotSeptember 2026146 min read TL;DR When DeepSeek-V4.1 Flash was released, I thought it might just be a post-training iteration version... but after using it for a while, I found it reached nearly 420 Tokens/s in speed, and then Cui said all DeepSeek-V4 Pro models would be taken offline... suddenly I felt this was no small matter... until the Technical Report 《DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression》[1] was fully released, only then did I realize it should be called DeepSeek-V5 Flash... As the paper title states, the purpose of DeepSeek-V4.1 Flash is to push KVCache compression to the extreme.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at Github.
Discussion
0 commentsMore from Github