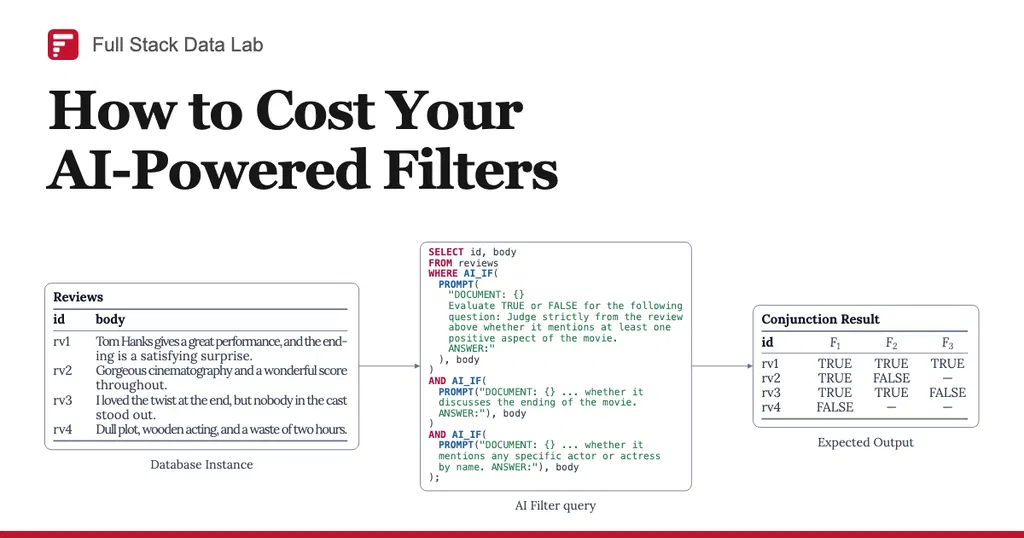
How to Cost Your AI-Powered Filters
Back to blog How to Cost Your AI-Powered Filters Oct 1, 2026 Arnav Dhariya, Shreya Shankar TL;DR: How fast could an AI-SQL query run on a given LLM and GPU? We walk through how to estimate speed-of-light (SoL) latency for individual filters and conjunctions of filters, providing a baseline for evaluating system performance. You can try out our interactive playground to explore how filter ordering affects estimated latency on Qwen3-4B and an H100.
- ▪Back to blog How to Cost Your AI-Powered Filters Oct 1, 2026 Arnav Dhariya, Shreya Shankar TL;DR: How fast could an AI-SQL query run on a given LLM and GPU?
- ▪We walk through how to estimate speed-of-light (SoL) latency for individual filters and conjunctions of filters, providing a baseline for evaluating system performance.
- ▪You can try out our interactive playground to explore how filter ordering affects estimated latency on Qwen3-4B and an H100.
2 outlets in our directory ran this story, first to last over 34 hours. All of the coverage we found sits in one bucket: centre. That one-sidedness is itself worth noticing.
- ▪ AdultFriendFinder cost: How much it is, how it bills — Mashable
Hacker News (AI / LLM) files mainly under ai. We currently carry 7,212 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | Full Stack Data Lab |
| Canonical URL | https://fsdatalab.github.io/blog/ai-filter-cost-estimates/ |
| Publication time | Thu, 01 Oct 2026 19:12:53 +0000 |
| Retrieval time | 2026-10-01T19:22:19.650Z |
| Last seen | 2026-10-01T19:22:19.650Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | ZTEF1I83zr1V · 2 stories |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
Back to blog How to Cost Your AI-Powered Filters Oct 1, 2026 Arnav Dhariya, Shreya Shankar TL;DR: How fast could an AI-SQL query run on a given LLM and GPU? We walk through how to estimate speed-of-light (SoL) latency for individual filters and conjunctions of filters, providing a baseline for evaluating system performance. SoL estimates power Quail's cost models. You can try out our interactive playground to explore how filter ordering affects estimated latency on Qwen3-4B and an H100. Contents Introduction. Background. AI-powered filters. GPU Execution. Transformer Forward Pass. Roofline Model & Speed of Light. Cost Model for One Filter. Workload and Notation. Projection Cost. Attention Cost. MLP Cost. Total Cost. Cost of One IMDB Filter. Cost Model for a Conjunction of Filters.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at Full Stack Data Lab.
Discussion
0 commentsMore from Full Stack Data Lab