The Shift from Models to Compound AI Systems
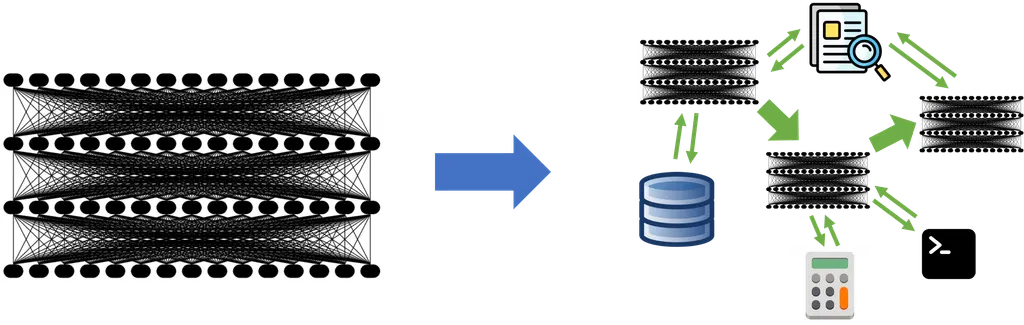
The focus of AI development is shifting from relying solely on large language models to building compound systems that integrate multiple components like retrievers and external tools. This approach allows developers to achieve state-of-the-art results through clever engineering and dynamic data access rather than just scaling up model training. The article argues that compound AI systems will likely remain the dominant paradigm for maximizing AI performance in high-value applications.
- ▪State-of-the-art AI results are increasingly obtained by compound systems with multiple components rather than monolithic models.
- ▪Google's AlphaCode 2 uses a system that generates up to 1 million possible solutions and filters them to achieve superior programming results.
- ▪Databricks found that 60% of LLM applications use retrieval-augmented generation and 30% use multi-step chains.
- ▪Compound systems allow for dynamic knowledge incorporation and access controls that static models cannot provide.
- ▪Engineering compound systems often offers better returns on investment and faster iteration times compared to scaling model training budgets.
Hacker News (AI / LLM) files mainly under ai. We currently carry 6,494 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | The Berkeley Artificial Intelligence Research Blog |
| Canonical URL | https://bair.berkeley.edu/blog/2024/02/18/compound-ai-systems/ |
| Publication time | Fri, 25 Sep 2026 22:43:35 +0000 |
| Retrieval time | 2026-09-25T22:50:24.633Z |
| Last seen | 2026-09-25T22:50:24.633Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | MfLNO7gt49Dm · 1 stories |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
AI caught everyone’s attention in 2023 with Large Language Models (LLMs) that can be instructed to perform general tasks, such as translation or coding, just by prompting. This naturally led to an intense focus on models as the primary ingredient in AI application development, with everyone wondering what capabilities new LLMs will bring. As more developers begin to build using LLMs, however, we believe that this focus is rapidly changing: state-of-the-art AI results are increasingly obtained by compound systems with multiple components, not just monolithic models. For example, Google’s AlphaCode 2 set state-of-the-art results in programming through a carefully engineered system that uses LLMs to generate up to 1 million possible solutions for a task and then filter down the set.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at The Berkeley Artificial Intelligence Research Blog.
Discussion
0 comments