
A 7B fact-checker beat 30B LLM reviewers and deleted no true claims
Writes about data science, MLOps, and open-source tooling. Have you ever asked one model to summarize something, then used another model to check whether the summary was trustworthy? I used a local model to summarize meeting transcripts I couldn’t attend.
- ▪Writes about data science, MLOps, and open-source tooling.
- ▪Have you ever asked one model to summarize something, then used another model to check whether the summary was trustworthy?
- ▪I used a local model to summarize meeting transcripts I couldn’t attend.
Hacker News (AI / LLM) files mainly under ai. We currently carry 5,917 of its stories.
Story provenance
Source · retrieval · rights · ranking — open for full record
inspect →
Story provenance
Attribution is not the same as permission. This drawer separates discovery metadata, excerpts, WeSearch-generated summaries, reuse status, and whether the publisher receives the visit. Nothing here claims a legal grant the publisher has not made.
Record
| Original publisher | Hacker News (AI / LLM) |
| Canonical URL | https://openteams.com/llm-review-reliability/ |
| Publication time | Tue, 22 Sep 2026 02:18:22 +0000 |
| Retrieval time | 2026-09-22T02:58:49.462Z |
| Last seen | 2026-09-22T02:58:49.462Z |
| Headline source | Publisher (no WeSearch rewrite) |
| Excerpt source | publisher body |
| Excerpt method | First ~120 words (~800 chars) of extracted publisher body, fair-use limited. |
| Summary | WeSearch · cerebras-chat (WeSearch summarizer) |
| Summary source text | contentText |
| Citation coverage | Summary is a WeSearch-generated derivative; primary citation is the original publisher URL. |
| Cluster | mlKoN8_C1S1s · 1 stories |
| Cluster logic | Grouped by semantic title/content similarity across sources within a rolling window. Same-publisher template collisions are excluded from coverage comparison. |
| Ranking reason | Story pages are not engagement-ranked. Hub feeds use recency, with optional source-diversified chronological ordering (cap consecutive stories per source). No personalized ranking. |
| Publisher visit | Yes — open original |
| Substitutes article? | No — link-out required for full text |
Rights status (four layers)
WeSearch handling by dimension
| Indexing | May the item be indexed (stored, ranked, made findable)? | Allowed |
| Snippet | May a short excerpt of the publisher's text be shown? | Allowed |
| AI summary | May WeSearch generate its own short summary of the article? | Limited |
| Retrieval / RAG | May the content be exposed for third-party retrieval-augmented generation? | Not asserted |
| Model training | May the content be used to train AI models? | Not asserted |
| Commercial reuse | May the content be reused commercially? | Not permitted |
Basis: Derived from the published RSS/Atom feed. Contact: [email protected]. Reviewed: 2026-07-24.
Opening excerpt (first ~120 words) tap to expand
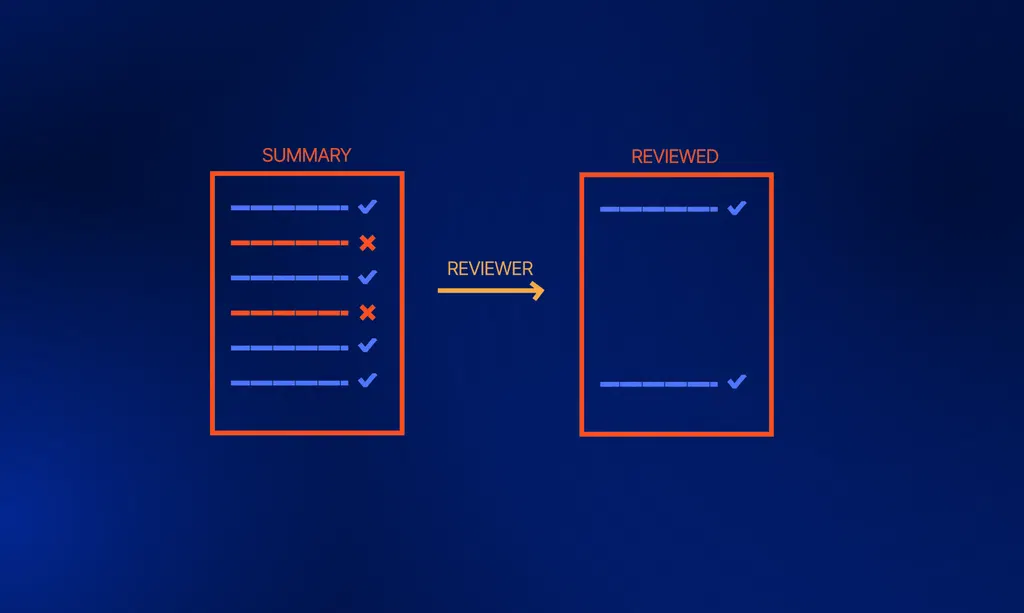
Khuyen Tran Senior DevRel at OpenTeams. Writes about data science, MLOps, and open-source tooling. Have you ever asked one model to summarize something, then used another model to check whether the summary was trustworthy? I have. I used a local model to summarize meeting transcripts I couldn’t attend. When I read the summaries, I noticed claims that were not in the meetings at all. I didn’t want to check every claim myself, so I asked a second model to review the summaries for me. I expected the reviewer model to do well. After all, checking a summary should be easier than writing one. This article walks through what I found. TL;DR Here is the short version: A reviewer is not automatically a safety layer.
…
Excerpt limited to ~120 words for fair-use compliance. The full article is at Hacker News (AI / LLM).
Discussion
0 commentsMore from Hacker News (AI / LLM)


