Hugging Face - Blog
ai · source
Hugging Face Blog on WeSearch
Recent ai headlines from Hugging Face Blog.
Lead story
Hugging Face Blog
The Agent Said It Was Done. The Database Disagreed.
Enterprise Article Published October 3, 2026 Upvote - Tuhin Kundu tuhink Follow microsoft A tool call is not an outcome One success is not reliability Can you depend on the model behind your agent? Figure 1:…
The latest
Hugging Face Blog
Turning Database Grading into RL Rewards: Post-Training Agents with ThinkingBox
Hugging Face Blog
OlmoEarth v1.3: State-of-the-art embeddings for the whole planet
Hugging Face Blog
Ensemble forecasting with IBM Granite time-series models
Hugging Face Blog
NVIDIA Kumo Relational Outperforms Supervised Machine Learning on Relational Data, No Training Required
Hugging Face Blog
Train in Simulation, Deploy on a Real Robot: Microduck with Isaac Lab 3.0
Hugging Face Blog
How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications
Hugging Face Blog
Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.
Hugging Face Blog
Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.
Hugging Face Blog
Granite Speech 5.0: Transcribe, Translate, and Attribute more Accurately and Faster
Hugging Face Blog
NVIDIA Kumo Forecast Combines Pretrained Time-Series Representations with Historical Pattern Retrieval and Interpretability
Hugging Face Blog
Protein Design with RFD4-Proteina and Hugging Face Spaces
Hugging Face Blog
Announcing SimReady Central: An Open Library of Simulation-Ready 3D Assets for Robotics and AI Factories
Hugging Face Blog
NVIDIA Nemotron 3.5 Embed, Rerank, and Parse: Advancing Agents with World-Class Retrieval Models
Hugging Face Blog
NVIDIA Cosmos3-H-Dreams: Bringing Clinical Surgery to Life Through Generative Simulation
Hugging Face Blog
FairStress: A deeper evaluation of fairness in LLM decision-making
Hugging Face Blog
ALTK-Evolve: How learned memory tops the τ²-bench leaderboard on customer service tasks without a frontier model
Hugging Face Blog
Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline
Hugging Face Blog
Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
Hugging Face - Blog
HiRO-ACEv2: Simulating extreme weather at 3 km resolution for a fraction of the cost
Hugging Face Blog
Run fast, private agents on-device with LFM2.5-24B-A2B

Hugging Face Blog
Open-sourcing AstaBrief, the fast report-generation model in Asta
But scientific work places particular demands on these models—answers need to stay grounded in evidence, the models…
Hugging Face - Blog
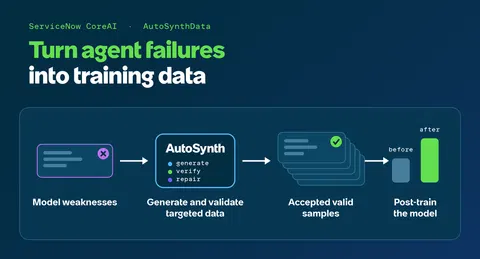
AutoSynthData: Generating Training Data for Enterprise Agents
ServiceNow CoreAI has developed AutoSynthData, a pipeline that converts model capability gaps into high-quality…

Hugging Face Blog
Introducing Olmo-core 3: Open, scalable training infrastructure for large MoEs
Olmo-core 3 is designed to scale MoE training into the trillion-parameter range while preserving computational…

Hugging Face Blog
NVIDIA Kumo Tabular Sets a New Accuracy-Efficiency Frontier for Tabular Prediction
Given a table of labeled rows, it predicts the labels of new rows in a single forward pass, with no training, no…

Hugging Face Blog
Getting the Source Right, Not Just the Fact: Source-Aware Verification for MCP Agents
Through the Model Context Protocol (MCP), an agent can call a search tool, inspect a structured patient or account…

Hugging Face Blog
Holo4: powering generalist computer-use agents
It comes in two sizes: 27B dense and 35B-A3B Mixture of Experts. We are also releasing an updated version of Holotron…
Hugging Face Blog
Accelerating vision-language models with LFM2.5-VL-DSpark
As with our recently released LFM2.5-DSpark drafter models, it adds a speculative decoding path that trades a minimal…

Hugging Face Blog
How to Use NVIDIA Warp and MjWarp to Accelerate Robotics Simulation and Learning Workflows
Basic usage: structs, batch sizes, and a minimal step Performance tuning Workflow to migrate a MuJoCo scene to MjWarp…

Hugging Face Blog
**Know Who Spoke When: Build Real-Time, Multi-Speaker AI with NVIDIA Nemotron 3 Diarization**
NVIDIA has released Nemotron 3 Diarization, an open-weight model designed to identify which speaker is talking in…

Hugging Face Blog
Pruning LLMs Like a Physicist: Block Removal as an Ising Optimization Problem
Because the model literally gets shorter, block removal (also called depth pruning) buys predictable inference…
Hugging Face Blog
Your Agent Aced the Task. Will It Do It Again?
In production, it is a reliability problem: a workflow that succeeded once may fail the next time a user makes the…

Hugging Face - Blog
Record, train, and deploy from one place with Strands Agents, LeRobot, and Hugging Face Storage Buckets
You have an agent that can already record a demonstration and push it to the Hugging Face Hub. Now you want to run…

Hugging Face Blog
Build Low-Latency Multilingual Voice Agents: Open Weights & Full Deployment Control with NVIDIA Magpie TTS
By the time a user hears your application respond, you've already spent precious milliseconds capturing audio,…

Hugging Face Blog
Making Knowledge Distillation Cheap Enough to Run at Scale
With the recent wave of open-source Large Language Models, such as gpt-oss, Qwen, GLM, or Kimi, it has become a…

Hugging Face Blog
TutorMoments: Do AI tutors know when to help and when to hold back?
Back to Articles TutorMoments: Do AI tutors know when to help and when to hold back? Enterprise Article Published…

Hugging Face - Blog
Deploy local agents everywhere with LFM2.5-2.6B
It supports tool calling and multi-step workflows while staying small and fast enough for everyday hardware, from…

Hugging Face Blog
GPU Management: Why Idle GPUs Are the New Grounded Aircraft
The Bottleneck Moved From Models to Compute Why Busy Clusters Still Waste Capacity Intelligence Moves Into the…
Hugging Face - Blog
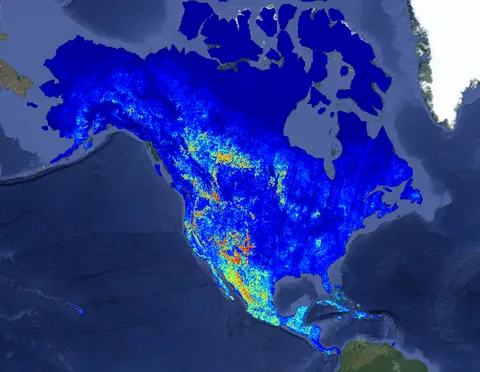
The OlmoEarth Platform: Geospatial inference at planetary scale
Governments, NGOs, and other mission-driven organizations are already adapting OlmoEarth for applications including…

Hugging Face Blog
LFM2.5-Encoders for Fast Long-Context Inference on CPU
They match the quality of larger models but stay fast as inputs get longer. This means you can run document-scale jobs…

Hugging Face Blog
NVIDIA Cosmos-H-Dreams: Bringing Real-Time Generative Simulation to Surgical Robotics
Back to Articles NVIDIA Cosmos-H-Dreams: Bringing Real-Time Generative Simulation to Surgical Robotics Enterprise +…
Hugging Face - Blog
The State of Simulation for Physical AI: An Overview
MuJoCo MuJoCo Warp Isaac Sim Isaac Lab How Isaac Lab 3.0 Relates to Isaac Sim and Newton Modern GPU-Accelerated…
Hugging Face - Blog
LeRobot v0.6.0: Imagine, Evaluate, Improve
LeRobot v0.6.0 introduces new features to improve robot learning, including world model policies that imagine the…
Hugging Face - Blog
Why Specialization Is Inevitable
Specialization is a defining principle of effective AI systems, and it is predicted by optimization theory,…
Hugging Face - Blog
Which tokens does a hybrid model predict better?
Back to Articles Which tokens does a hybrid model predict better? Enterprise Article Published June 25, 2026 Upvote -…

Hugging Face - Blog
NeuroBait: I fine-tuned a model to spark dopamine for ADHD brain
Back to Articles NeuroBait: I fine-tuned a model to spark dopamine for ADHD brain Team Article Published June 9, 2026…

Hugging Face - Blog
Amazing Digital Dentures (a failed project)
The Amazing Digital Dentures project was inspired by an animated show and aimed to create a digital pet that sends…

Hugging Face - Blog
Sponsors especially OPENAI CODEX voucher usage for codex - openAI challange
The article discusses the challenges participants face in activating their OpenAI Codex vouchers for a hackathon. It…

Hugging Face Blog
Direct Preference Optimization Beyond Chatbots
The article discusses advancements in Direct Preference Optimization (DPO) for improving text transcription accuracy…
How WeSearch handles this source
WeSearch's declared handling of Hugging Face Blog's content. Indexing, snippets, summaries, retrieval and training are separate questions — see the rights registry or read this source's machine-readable record.
Indexing: Allowed
Snippet: Allowed
AI summary: Limited
Retrieval / RAG: Not asserted
Model training: Not asserted
Commercial reuse: Not permitted